AI Content Engine Architecture for Marketing Teams
How AI answer engines decide what to cite, and why your content strategy needs to change.
A page can lose Google clicks and gain citations in ChatGPT in the same quarter, and a page that never ranked on Google at all might get named by an AI answer engine on a regular basis. That split is the subject of this piece: marketing and content teams are losing or gaining visibility through a channel most of them still cannot measure, and the architecture built to win traditional search does not automatically win this one.
The mechanism driving that split is retrieval-augmented generation. When someone submits a query to an AI answer engine, the system first retrieves a set of candidate documents, then a large language model synthesizes those documents into a single composed answer. There is no ranked list of ten blue links here. Content is either woven into that composed answer or left out of it entirely, with no middle position to occupy and no page two to fall back on. Being named inside the answer is now the event that matters: no click follows, no impression gets logged, and no awareness accrues to a brand the model did not choose to mention.
This is why the familiar shorthand, treating "AI search" as just another ranking factor layered on top of SEO, misreads what's happening. Search engine optimization still governs ranked results on a results page. Answer engine optimization and generative engine optimization describe a separate task: getting named inside a generated response where there is no position to climb, only inclusion or exclusion. AI systems build an internal model of a topic by mapping entities, relationships, and the breadth of coverage across a domain. They are not matching a query against keyword density on a single page, which is the basic move traditional search still rewards. A content engine built only to satisfy that older match is optimizing for a mechanism the newer surface does not use.
Signals AI systems use to decide which brands to cite
If citation is the conversion event, then the signals that drive citation are what any content engine needs to be built around. Four stand out as load-bearing: brand mentions, source diversity, freshness, and passage-level structure. The content engine leaves citation share on the table that a more complete system would have captured.
Start with brand mentions. Ahrefs studied 75,000 brands and found that brand mentions correlate far more strongly with AI visibility than backlinks do. That finding cuts against years of SEO instinct, where link-building was treated as the primary lever for authority. AI systems appear to weigh being talked about, by name, across the web, more heavily than being linked to. Source diversity compounds that effect: brands with a presence spread across multiple kinds of sources (review sites, forums, industry press, video) show substantially higher average AI coverage than brands that depend on a single source type. A brand that lives only on its own domain, no matter how well that domain is optimized, is working from a narrower base than a brand present across several kinds of platforms at once.
Passage structure works at a finer grain than most SEO practice does. AI systems don't rank a page. They extract specific passages that answer specific sub-questions. A page built as one long, well-rounded overview is harder to pull from than a page built as a sequence of self-contained answers. ConvertMate's GEO Benchmark 2026 found that 44.2% of LLM citations come from the first 30% of a page's text, a concentration that makes the opening of a section a structural requirement. The practical implication is that each H2 on a page needs to function as its own answer snippet: a question-shaped heading, an opening sentence that states the answer immediately, and a named source attached to the claim. A content engine that understands these four signals, brand mentions, source diversity, freshness, and passage structure, has a target to build toward. One that doesn't is guessing.
Why a single AI tool falls short of a content engine
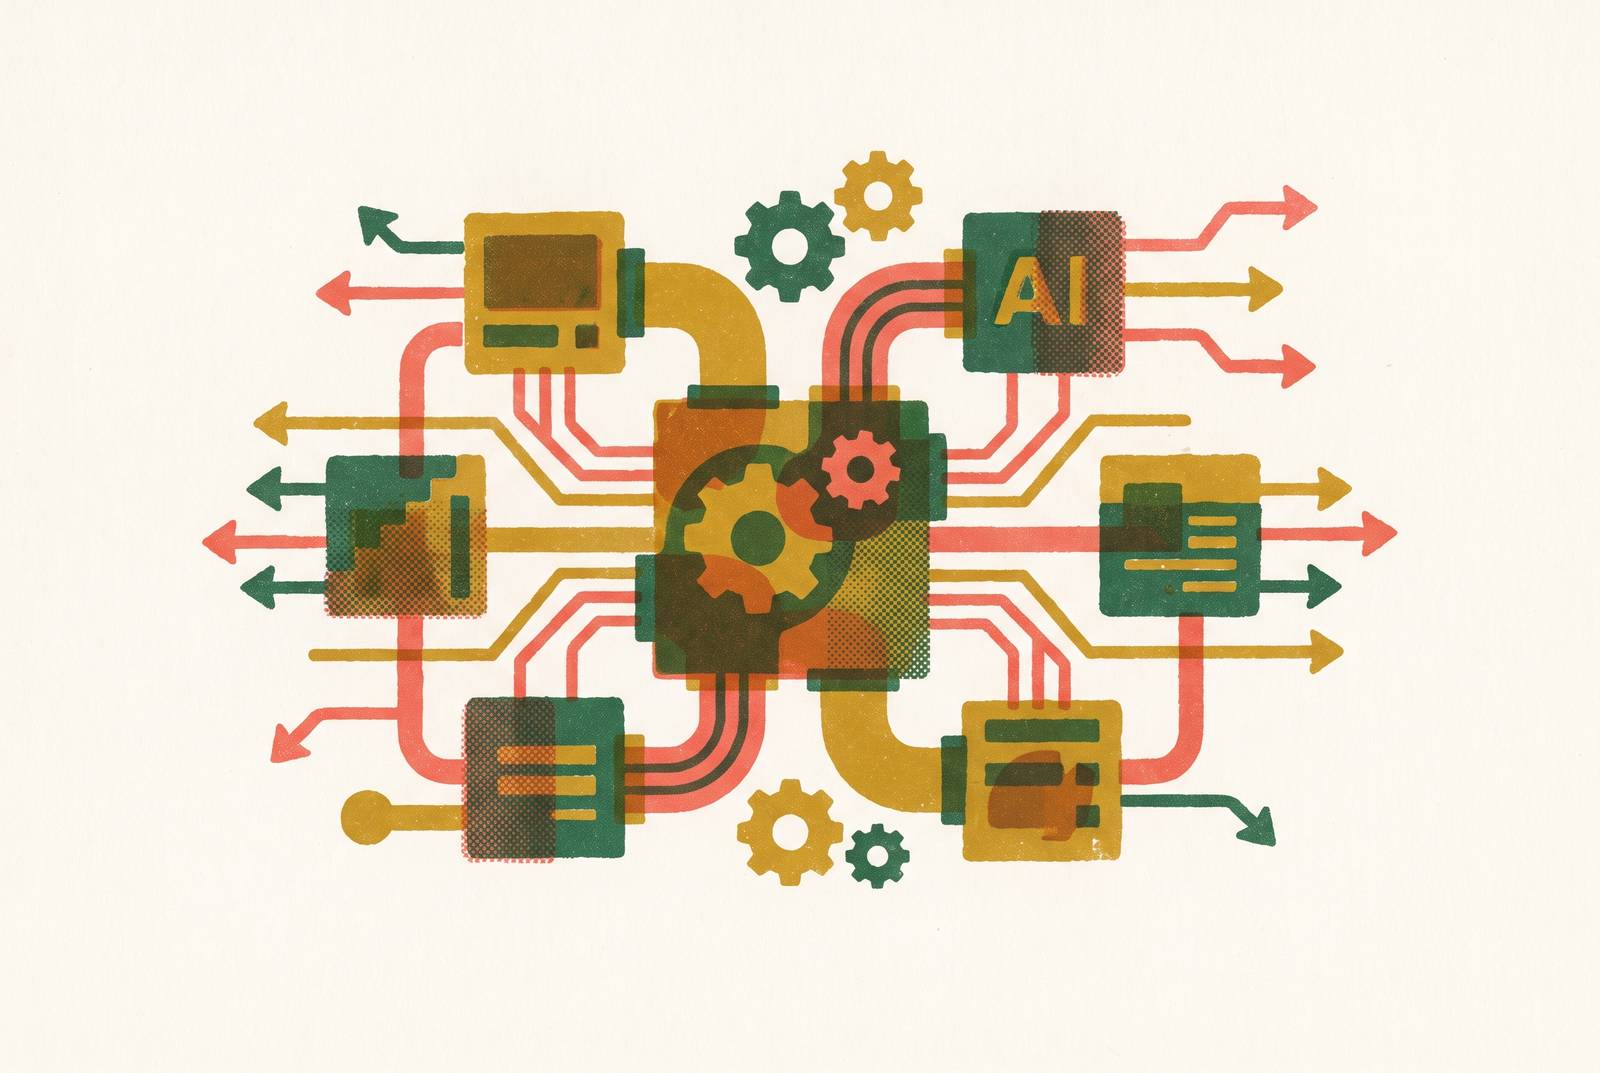
The gap between teams that build AI citation authority that compounds over time and teams that just produce a lot of content is almost always a matter of architecture. Teams in the first group run a coordinated pipeline made up of specialized components with human checkpoints built in. Teams in the second group run a single drafting tool with nothing upstream feeding it research and nothing downstream measuring what happened after publication.
A single AI drafting tool can turn out text fast. What it cannot do is guarantee that the text is built from retrievable, citable sources, or that it satisfies the freshness, source-diversity, and passage-structure signals described above, because none of those signals are things a drafting step alone can produce. They require decisions made before drafting starts and checks made after it ends. A drafting tool answers a prompt. A pipeline enforces a standard across every piece of content a brand produces, no matter the scale that brand operates at. And the honest bottleneck in a well-built pipeline is never how fast the AI can draft. It's how much review capacity the humans on the team have, which is the design constraint the rest of this piece is built around.
The research layer: how a content engine builds topic authority before drafting begins
A content engine that starts its process at the drafting stage has already made its most consequential mistake, because topic authority in AI answers comes from systematic, multi-angle coverage of a domain, and that kind of coverage has to be planned before a single draft gets written.
The practical work of this layer starts with auditing existing content by topic cluster. For each topic a brand wants to own, the research layer maps the actual sub-questions users are asking about it, then checks which of those sub-questions have no content directly answering them. Those unanswered sub-questions are the gaps this discipline exists to close. This is also where source strategy gets decided: which third-party platforms, Reddit threads, review sites, trade publications, deserve a deliberate, sustained presence for a given topic cluster, based on where AI systems are already pulling citations for that category today. Skipping this step doesn't just slow a team down. It means every later layer of the pipeline is drafting, reviewing, and publishing against a guess instead of a map.
Two functions anchor this layer. The first is topic-cluster mapping itself, the ongoing exercise of identifying what a brand should own and what gaps exist inside that territory. The second is a standing watcher function, an automated monitor that surfaces relevant developments in a topic area as they happen, feeding the editorial calendar continuously instead of waiting for a quarterly audit to catch up. Research is also where the first of four non-negotiable human gates belongs: brief approval before any work begins. No draft should start without a human confirming that the brief reflects a real gap and a real priority, because a well-drafted piece built against the wrong brief is still wasted effort, just wasted more convincingly.
The drafting layer: passage structure and source provenance
Everything the research layer maps out has to be translated into a draft, and drafting for AI citation authority asks for a different discipline than drafting for engagement or for keyword density. That discipline includes answer-first passages, named sources attached to specific claims, and comparison tables where a comparison is the actual content of the claim. A content engine has to build this discipline into its prompts and its templates directly, rather than hoping individual writers apply it consistently on their own.
The evidence for this different discipline is specific. Researchers at Princeton University, IIT Delhi, Georgia Tech, and the Allen Institute for AI published a 2024 paper showing that generative engine optimization techniques, structured formats, concise direct answers, claims backed by evidence, measurably increase how often content gets surfaced in AI responses, while keyword stuffing performed below baseline. A sentence that says a product is "popular" gives a retrieval system nothing to grab. A sentence that states a specific number, with a named source behind it, gives the system something it can quote directly. Every H2 section, as the earlier section on signals laid out, should work as its own standalone answer: a question-shaped heading, an answer stated immediately in the first sentence, and a named source attached to that answer.
One more requirement belongs at the drafting layer, and it's a legal one, not a style preference. The U.S. The Copyright Office's Part 2 report states that AI-assisted outputs are protected by copyright only where a human author has determined sufficient expressive elements. A defensible pipeline keeps a provenance log that records human editorial judgment at each stage of a piece's production, along with a source citation for every factual claim the piece makes. Without that log, a brand publishing AI-assisted content at volume has no record showing where human judgment entered the process, which is the exact record a copyright claim would need. In this architecture, senior writers stop drafting every individual piece themselves and become owners of the system prompts, style guides, and exemplar pieces that keep this structural standard consistent across everything the pipeline produces.
The human review layer: where gates go, what they check
Four human gates separate a production-grade pipeline from a content factory with no oversight, and none of them function as a checkbox. Each one is a point where a human judgment call decides whether a piece is accurate, on-brand, legally sound, and worth putting the brand's name on.
Those four gates, drawn from how practitioners actually run these pipelines, are: brief approval before any work begins, an outline check after research and before drafting starts, a pre-publish review before anything goes live, and a post-publish performance trigger that kicks in when a piece underperforms and needs to be reworked. The bottleneck in a mature pipeline is never generation speed. It's review capacity, and that constraint is why consistency work needs to move upstream, into the prompts, style guides, and shared brand assets described in the drafting section, so reviewers spend their time on genuine judgment calls instead of catching the same repeatable error over and over.
The results of running review this way are measurable. One organization produced more than 200 AI-assisted assets in under five weeks and cut major revision requests by nearly 69% compared to an earlier cycle that ran on a much looser approval structure. That drop in revisions is what tiered, role-based review is supposed to produce: fewer surprises reaching the final gate because earlier gates already caught them. The principle is visible at the infrastructure level too. Sanity's Content Agent, which went generally available in January 2026 and runs on Mastra and Temporal, stages every change as a draft before it ever touches production. Contentful runs bulk AI changes through a review screen where a team approves, declines, or adjusts suggestions before they apply. Both are the same idea built into the content management system itself: every AI-generated suggestion stays reviewable and reversible before it ships, because automation should never cost a team the ability to say no to a specific piece of output. Roles shift accordingly. Junior writers move into fact-checking, provenance logging, and SEO pass approval, while content strategists move earlier in the process, owning intake and brief structuring against the team's pipeline contribution targets.
The publishing and distribution layer: owned content, third-party seeding, and technical access for AI crawlers
Where content lives, and whether the systems doing the citing can actually reach it, matters as much as how the content is structured, because most AI citations come from sources a brand doesn't own. A pipeline that only publishes to its own domain is optimizing for half of the surface at best.
The legitimate version of third-party seeding starts with identifying the specific external platforms, Reddit threads, review sites such as G2 and Capterra, trade publications, YouTube, where AI systems are already drawing citations for a brand's particular topic cluster. From there, the work is building a genuine, systematic presence on those platforms: publishing content that's actually useful where those conversations are already happening, not manufacturing mentions that don't reflect real engagement. That distinction matters because AI systems weighing source diversity are reading real activity across real platforms, and a presence built on manufactured mentions doesn't hold up the way a presence built on substantive participation does. Owned content, third-party seeding, and basic technical access for AI crawlers are not separate concerns bolted onto the end of a content process. They are the layer where everything the research, drafting, and review stages built either reaches the systems doing the citing, or doesn't.